Coinbase benchmark shows newer AI models caught less payment fraud than older versions
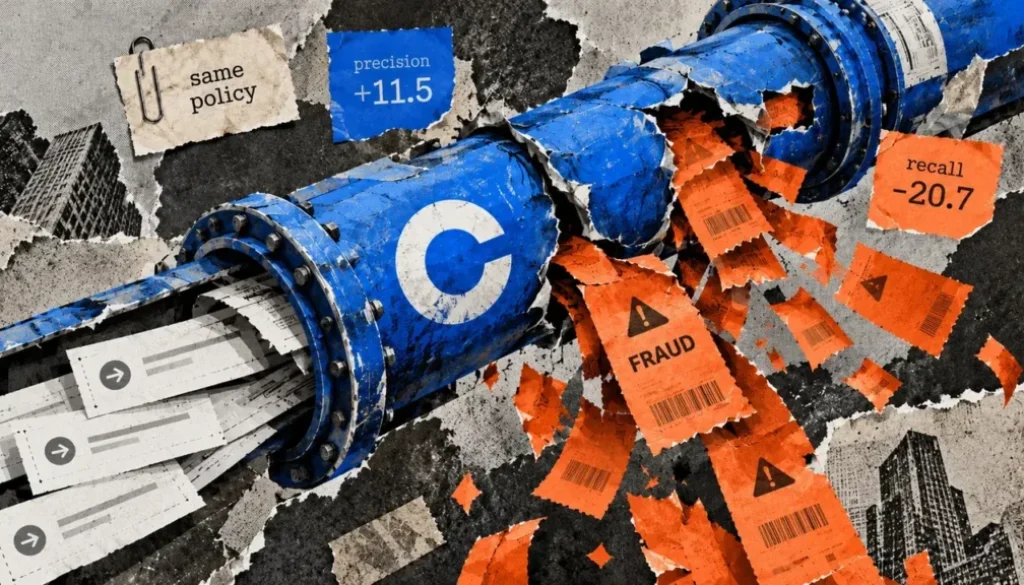
Coinbase’s fraud-detection benchmark reveals that newer versions of leading AI models performed worse at catching payment fraud, even as vendors promoted their improvements. The findings suggest that model upgrades alone cannot guarantee better fraud screening without careful validation in production conditions.
- Newer versions of Opus, Sonnet, and GPT caught fewer fraudulent transactions and lower fraud value in Coinbase’s historical replay test.
- Sonnet 5’s recall dropped 22.2 percentage points versus Sonnet 4.6, while Opus recall fell 0.8 points in the same evaluation framework.
- A custom post-trained Qwen model outperformed Opus 4.5 by 9.6 percentage points on F1 and 35.4 points on dollar-weighted recall.
- 22.2% Sonnet model recall decline, newer version versus prior
- 9.6% F1 score improvement, custom Qwen model versus Opus
- 55% Latency reduction for custom Qwen versus Opus inference
- 16,140 Transactions evaluated across 7,293 users in the test
CryptoSlate reported on October 7 that Coinbase tested three major AI model families against historical payment data and found that newer versions underperformed their predecessors at detecting fraud. The company evaluated 16,140 transactions across 7,293 users, including 813 confirmed fraudulent cases, using a fixed decision policy to isolate each model’s detection behavior. The test replayed nine weeks of payment activity before Coinbase’s risk agent deployed, holding constant both the screening rules and the classification-to-decision logic so that performance differences reflected only model capability changes, not system redesign.
Newer models caught fewer fraud cases across three model families
Coinbase compared Opus 4.5 with Opus 5, Sonnet 4.6 with Sonnet 5, and GPT-5.4 with GPT-5.6 in its benchmark. Recall, which measures the share of fraudulent transactions a model identifies, declined in every newer version. Sonnet’s recall fell 22.2 percentage points and its dollar-weighted recall, which tracks the proportion of total fraud value caught, dropped 22.9 points. Opus’s recall declined 0.8 points.
Both Sonnet and Opus also posted lower precision in their newer versions, meaning a smaller fraction of transactions they flagged as fraud were actually fraudulent.
GPT presented a more complex case: its precision rose 11.5 percentage points, making its fraud signals more accurate, but recall fell 20.7 points and dollar-weighted recall fell 21.8 points. The newer model was more selective in raising fraud flags, but more actual fraud slipped through detection in the replay. Coinbase acknowledged the test could not establish whether deploying those versions would cause actual customer losses, nor could the company pinpoint what drove the regressions.
A specialized small model outperformed standard larger models
Coinbase’s October 8 disclosure revealed that a post-trained Qwen3.5-9B model exceeded Opus 4.5 across four fraud-detection metrics. The company specialized the smaller model using historical fraud outcomes and deterministic rewards that balanced fraudulent and legitimate examples. Its F1 score, which combines precision and recall, improved 9.6 percentage points, and its dollar-weighted recall rose 35.4 points.
Production measurements showed the custom Qwen model achieved median end-to-end latency of 0.683 seconds versus 1.515 seconds for Opus 4.5, a 55 percent relative reduction.
Faster inference and stronger benchmark performance came from different optimization paths. Coinbase stressed that payment providers should first test whether a candidate model improves fraud coverage within their actual decision setup, then separately evaluate changes to prompts or decision thresholds, while also considering latency, reliability and cost alongside detection quality.
The BlockWest read. Coinbase’s findings expose a gap between vendor marketing and operational reality: model version numbers do not reliably correlate with production fraud detection. Teams deploying payment screening should resist upgrading on reputation alone and instead run their own historical replays on real transaction data before rollout, using fixed decision rules to isolate actual model improvement from system redesign.
The underlying research was first published September 23 and revised September 30. Payment service providers now have a concrete methodology to evaluate whether a new model version will actually catch more fraud under their existing policy before pushing it to production.
BlockWest is a news publication. Nothing here is investment advice. Read our disclaimer and editorial policy.